
Latest posts
-
The Alert That Never Fired: What a Default Zabbix Threshold Almost Cost Us
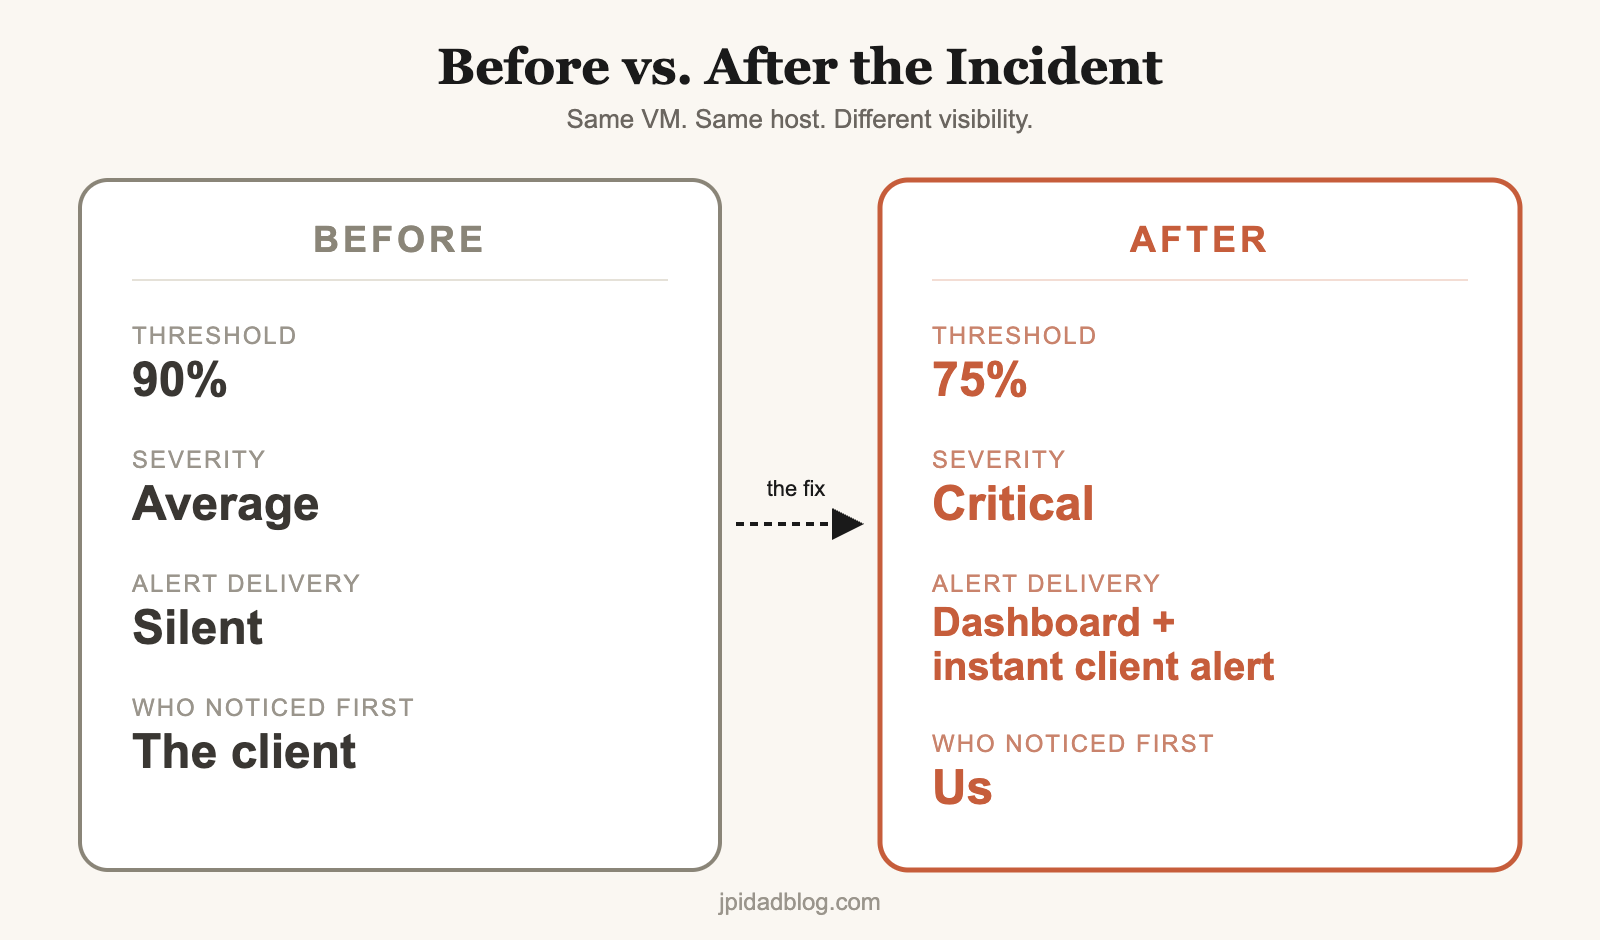
A default Zabbix alert threshold let a server go down unnoticed — we found out from the client. Here’s what changed after. The Incident One of the VMs we monitor for a client started having trouble on an otherwise normal day. CPU and memory usage spiked hard and fast, and because it was a VM…
-
VMware Snapshots Nobody Deleted: What I Found Reviewing a New Environment
I didn’t set out to do a VMware snapshots cleanup. I was just getting familiar with a new environment — and that’s exactly how I found snapshots that had quietly outlived whatever reason they were created for. The Environment The VMs in question had been in production since 2024, when a factory environment was first…
-
Windows Server Patch Tuesday: How I Sequence Rollouts to Avoid a Cascading Outage
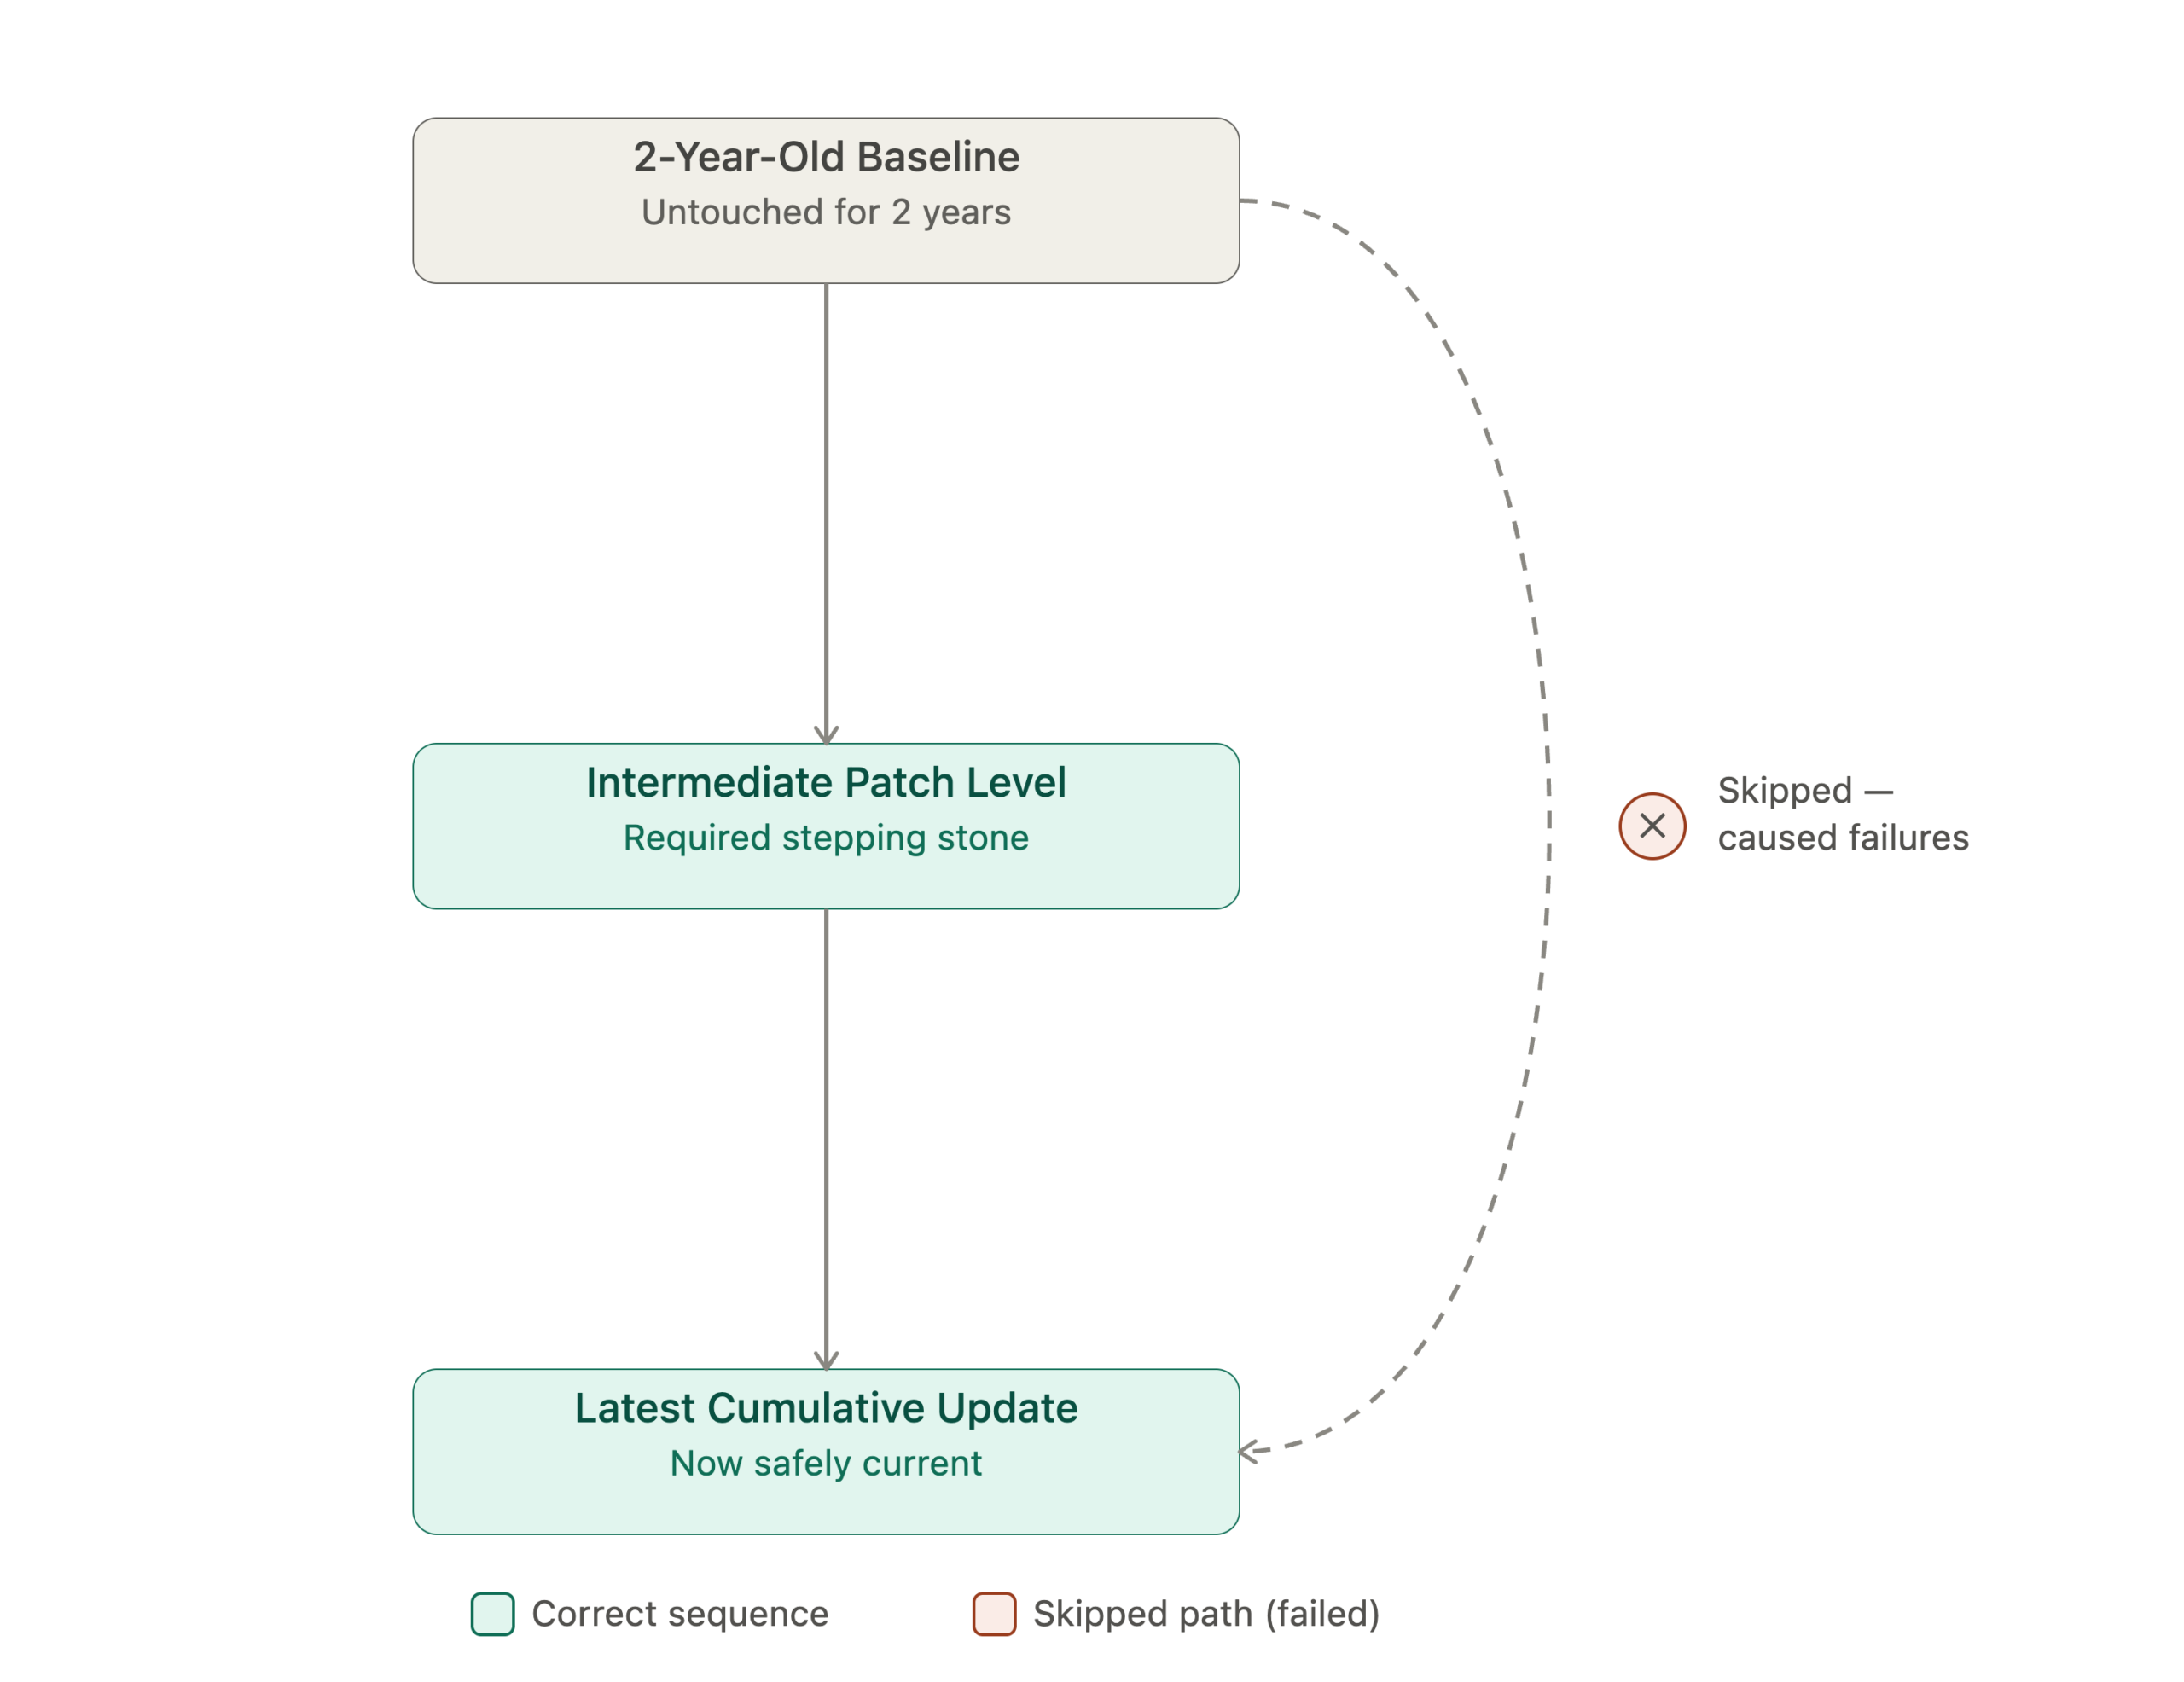
In a manufacturing environment, “just patch it” is rarely that simple. Patch the wrong server at the wrong time, and you’re not dealing with an IT ticket anymore. You’re explaining to the plant manager why the line stopped. Why I Still Patch Manually I deploy patches manually instead of relying on WSUS or SCCM. It’s…
-
The Day Our Backup Server Went Down: A Full Media Disk and a Corrupted NetBackup Config File
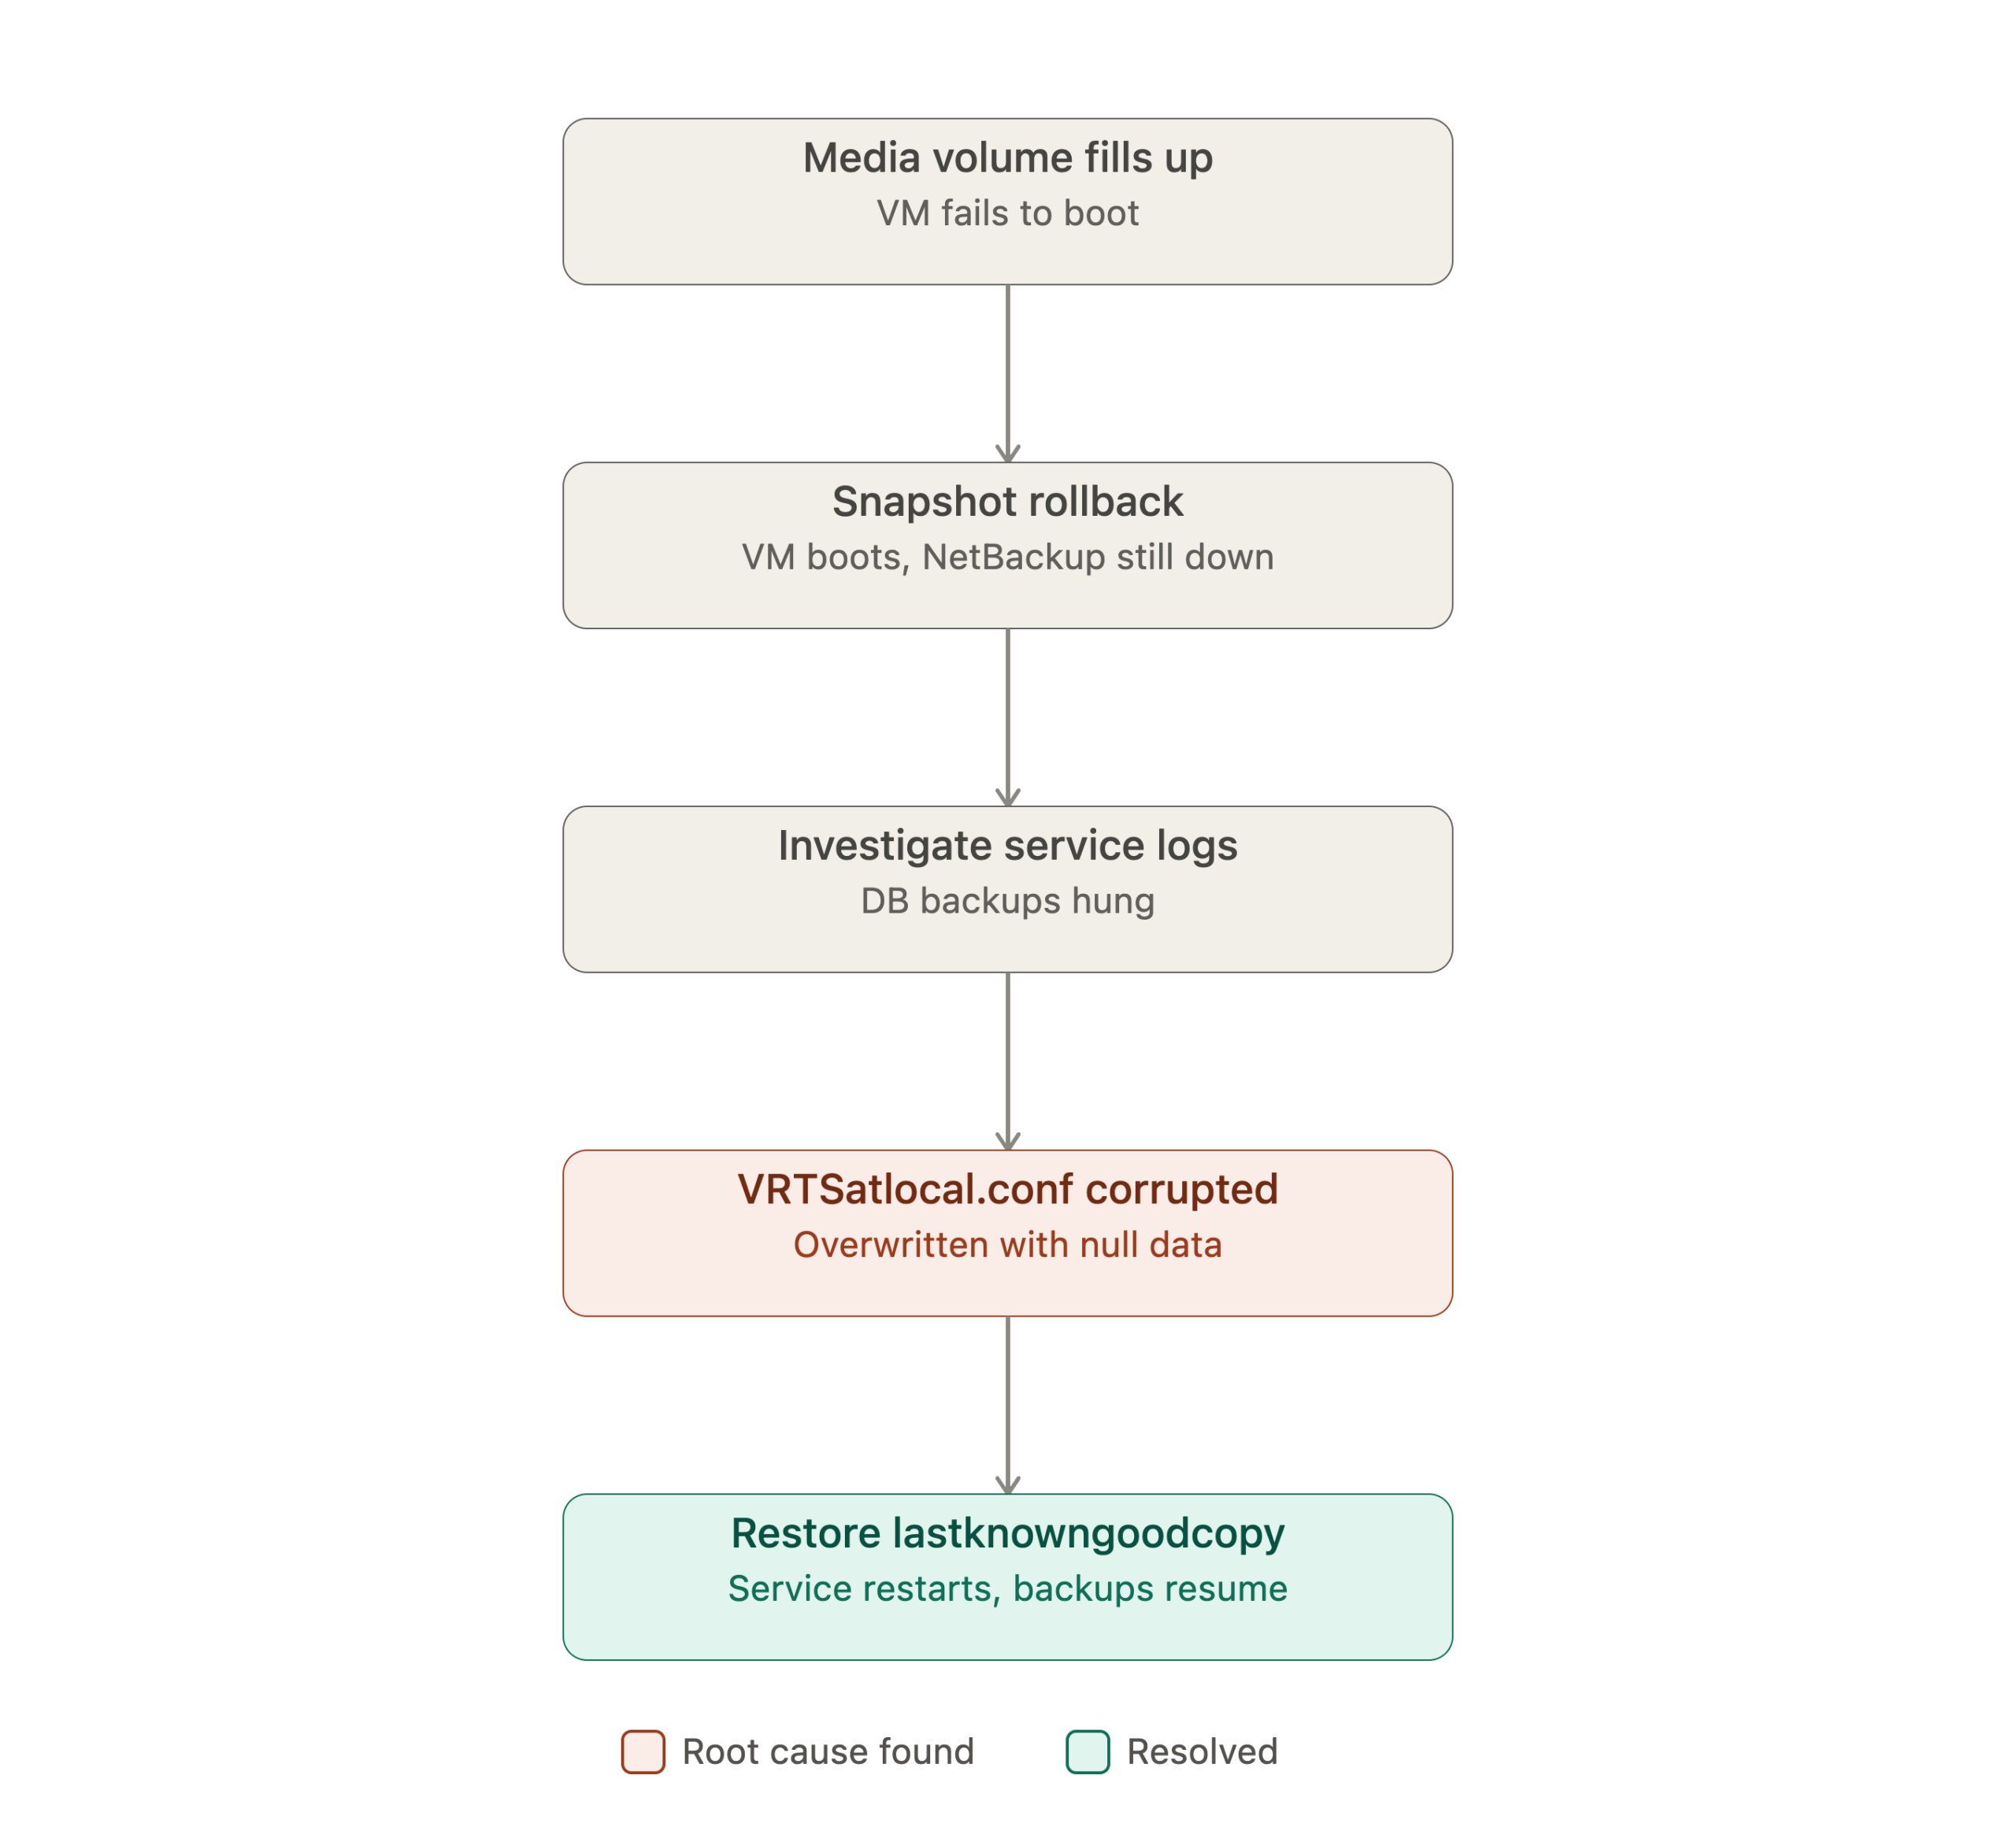
Not every backup failure shows up as a red X on a dashboard. Sometimes the backup server disappears before the alert even gets a chance to fire. What Happened We were running a lightweight NetBackup setup — not a dedicated appliance, just NetBackup installed on a Windows VM — with a media volume attached for…